
Mohamed bin Zayed University of Artificial Intelligence (MBZUAI) has introduced WorldGuide, a video world model designed to do something current video generators struggle with: plan what should happen next instead of simply following a fixed sequence.
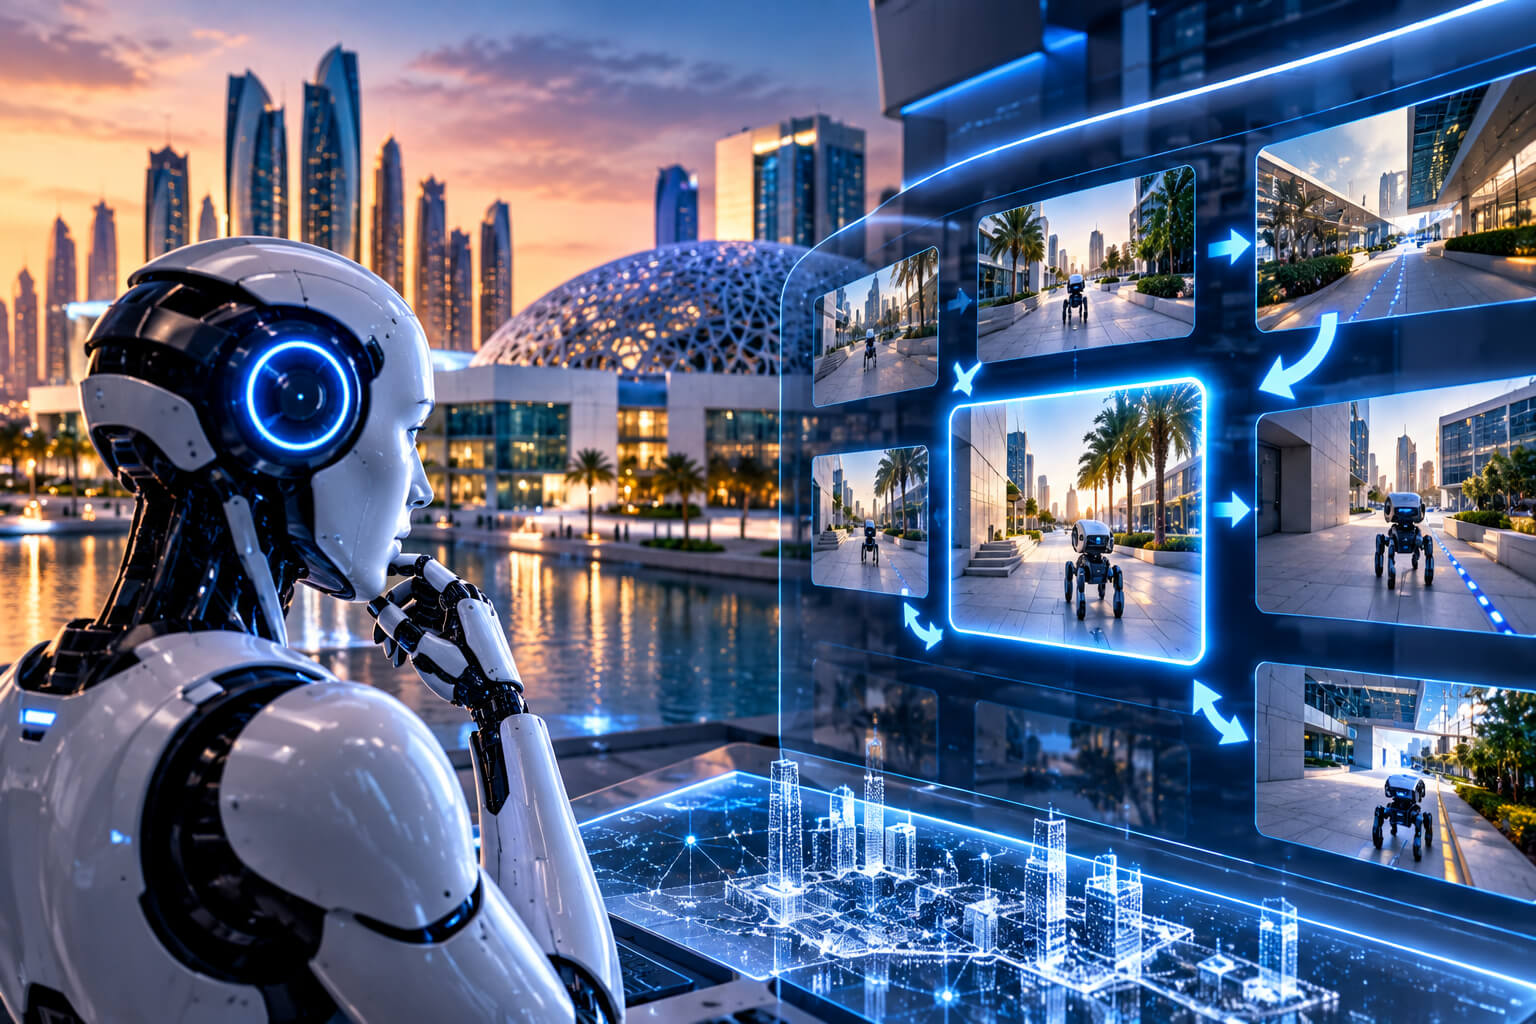
The system can start with an image and a task goal, generate a short video showing an action, examine what happened, and then select the next action. It can also decide when the task is complete.
That closed-loop approach is the interesting part. If a generated step goes wrong, WorldGuide can use the visual result to influence what comes next rather than blindly continuing with a predetermined plan.
WorldGuide Turns Video Generation Into a Step-by-Step Process
Most AI video systems focus heavily on generating convincing frames and maintaining visual consistency. WorldGuide takes a different route by treating video generation as part of a larger decision-making loop.
The model begins with an initial image and a goal, then repeatedly selects an action and generates a short clip representing that action. The generated result becomes feedback for the following step. This gives the system a basic form of planning, execution and self-checking within the same workflow.
The demonstrations cover procedural activities such as folding origami, assembling furniture and cooking, where completing the final objective requires several actions rather than one isolated generation.
Three Components Give WorldGuide Its Planning Loop
WorldGuide combines three main elements: a ContextPlanner, an Executor and hierarchical visual memory. Each handles a different part of the process, but they work together to maintain the sequence.
The ContextPlanner selects the next action or decides that the task has finished. The Executor then generates the video representing that action. The visual memory keeps information from earlier stages so the system does not have to treat every new step as if it were starting from scratch.
The ContextPlanner is built on Qwen2.5-VL-7B, while the Executor uses HunyuanVideo-1.5. MBZUAI researchers first trained and froze the planner before using its action representations to guide training of the video-generation component.
Visual Feedback Helps the Model Correct Its Course
The biggest conceptual change in WorldGuide is the feedback loop. Instead of generating a complete sequence based on instructions decided in advance, the system looks at its own output before choosing the next step.
That matters for procedural tasks because an early mistake can affect everything that follows. WorldGuide’s approach gives the model an opportunity to respond to what it has actually generated.
According to the reported experiments, closed-loop execution improved task success by 21.62% compared with an open-loop version. Adding visual feedback increased task success by another 18.61% and reduced repeated or skipped actions by 4.46%.
The numbers do not mean the problem is solved. They show that feeding generated visual results back into the planning process can make a measurable difference.
WorldGuide Bench Tests Whether Video AI Can Actually Complete Tasks
MBZUAI also introduced WorldGuide Bench, a benchmark designed specifically around procedural video tasks rather than judging generated video primarily on visual quality.
The benchmark contains around 59,000 procedural videos covering 245 tasks across 27 categories. The videos are broken into smaller action clips, with explicit signals indicating when individual actions have been completed.
That setup gives researchers a way to ask a more useful question: can a video world model actually maintain a sequence of actions and reach the intended outcome?
This is becoming an important distinction as video models move beyond entertainment and content creation toward robotics, simulation and interactive AI.
WorldGuide Recorded Higher Task Success Than MiniMax-H3
On WorldGuide Bench, the MBZUAI system achieved a 33.33% task-success rate, compared with 29.90% for MiniMax-H3. The comparison is notable because MiniMax-H3 was provided with reference action plans in the evaluation described by the researchers.
WorldGuide also recorded stronger results on Video-CraftBench, reaching 47.69% task success compared with 32.73% for MiniMax-H3.
The results are promising, but the relatively low absolute success rate on the main benchmark is just as important. Long, multi-step procedures remain difficult for AI. A model that can generate impressive individual clips still has to maintain the right objects, actions, order and end state across an entire task.
Visual Memory Helps WorldGuide Handle Longer Sequences
Long procedures create another problem: memory. As the number of generated steps grows, the system needs to retain useful information without allowing the computational cost to grow uncontrollably.
WorldGuide addresses this through hierarchical visual memory. Earlier parts of a sequence can be stored at progressively lower resolution, allowing the system to retain historical context while reducing memory requirements.
MBZUAI reported that visual memory improved performance by 5.77% on WorldGuide Bench. On Video-CraftBench, the reported improvement from visual memory reached 17.91%.
That makes memory more than a supporting feature. For world models, remembering what happened several steps ago can determine whether the next action makes sense.
MBZUAI Is Pushing Video AI Toward World Models
WorldGuide fits into a broader research direction at MBZUAI around models that understand environments rather than simply generate content. The university’s PAN world-model research similarly focuses on using language, video, spatial information and embodied actions to build representations of the world and support planning.
MBZUAI’s computer vision programme also identifies video generation, environmental-change prediction and robot navigation among its research areas.
WorldGuide takes that idea into a more procedural setting. The model is not merely asked to predict what a scene might look like. It is asked to generate a sequence that moves toward a goal.
WorldGuide Still Has a Long Way to Go
The research does not present WorldGuide as a finished autonomous system. MBZUAI’s reported results show that execution and stopping errors remain.
That limitation is important. A 33.33% task-success rate means most benchmark tasks still fail to reach the required outcome. The model can plan and react, but it does not yet demonstrate reliable long-horizon execution.
Still, the direction is significant. AI video research has spent years chasing sharper images, smoother motion and better prompt following. WorldGuide shifts some of that attention toward what the model does after it generates something.
That is a harder problem — and potentially a much more useful one.
World Models Could Connect Generative AI With Robotics
The longer-term significance of WorldGuide goes beyond AI-generated videos. A system that can represent actions, observe consequences and select another action is closer to the architecture needed for interactive agents.
That could eventually matter in areas such as robotics, simulation, autonomous systems and training environments. MBZUAI itself is already researching world models and embodied reasoning, while its current research programme covers applications including robotics and autonomous mobility.
For now, WorldGuide is still a research system. But it points toward an AI model that does not simply answer, “What should the video look like?”
It starts asking, “What should happen next?”
Sources
- Middle East AI News — MBZUAI builds video AI that plans its own next steps
https://www.middleeastainews.com/p/mbzuai-builds-video-ai-that-plans - MBZUAI — Inside PAN, MBZUAI’s groundbreaking world model
https://mbzuai.ac.ae/news-events/news/inside-pan-mbzuais-groundbreaking-world-model - MBZUAI — Computer Vision Research Programme
https://mbzuai.ac.ae/research/divisions/computing-mathematical-sciences-division/programs - MBZUAI — A faster way for AI to find and track objects in video
https://mbzuai.ac.ae/news-events/news/faster-way-ai-find-track-objects-video
